

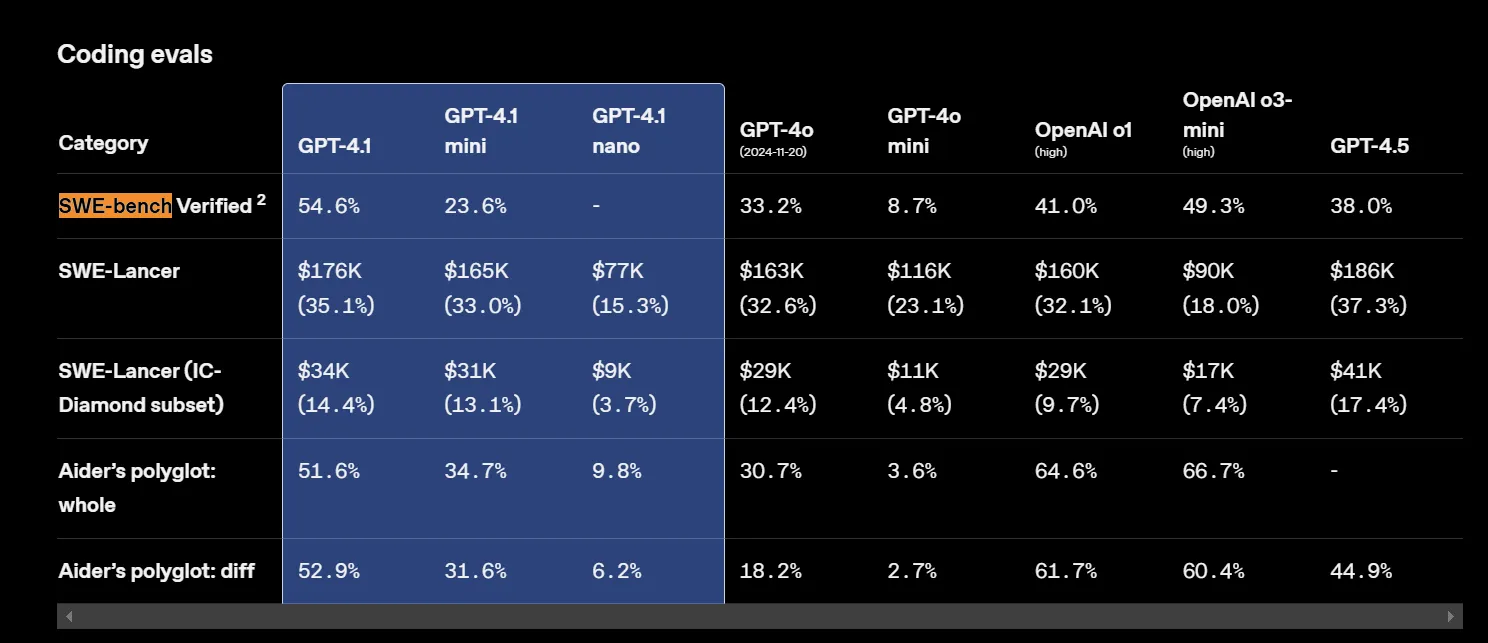
GPTunneL now offers the new GPT-4.1 family from OpenAI: GPT-4.1, GPT-4.1 mini, and GPT-4.1 nano. These models, recently released in the OpenAI API, build on GPT-4o and deliver noticeable improvements in performance and efficiency across a range of tasks.
Key features of GPT-4.1:
- Substantially improved coding quality (a 21.4% gain on the SWE-bench benchmark compared to GPT-4o).
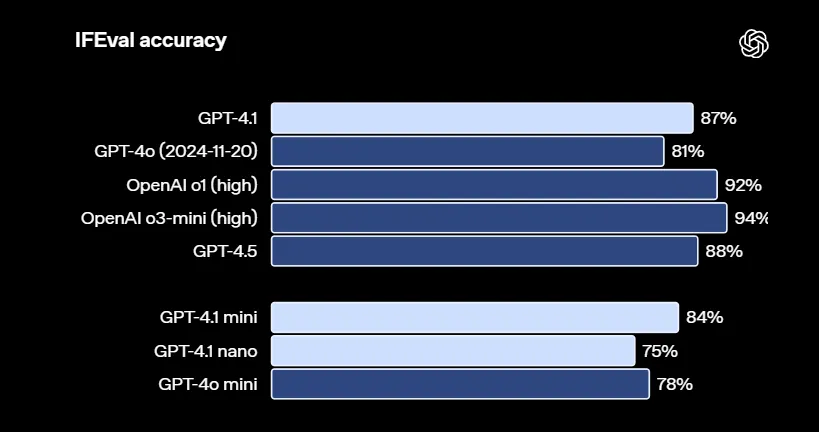
- More precise and stable instruction-following on complex tasks (87% on the IFEval benchmark vs. 81% for GPT-4o).
- Expanded context window of up to 1 million tokens for working with larger volumes of data.
- Improved efficiency: the mini and nano variants offer lower latency and cost for different use cases.
You can check the generation costs for GPT-4.1 models on our pricing page.
GPT-4.1-Mini and GPT-4.1-Nano
The family also includes smaller, more cost-efficient versions:
- GPT-4.1 Mini delivers performance that matches or even surpasses GPT-4o on a number of benchmarks, while running faster and costing 83% less.
- GPT-4.1 Nano is OpenAI's fastest and most affordable model to date, ideal for tasks where minimal latency is critical, such as data classification or rapid request processing.
All GPT-4.1 family models support a context window of up to 1 million tokens — significantly more than GPT-4o's 128 thousand tokens. This expanded context makes it possible to reliably process large volumes of information, for example analyzing extensive codebases or long documents, more effectively extracting the relevant details while ignoring irrelevant information.
Where GPT-4.1 can be useful:
- Software development: help with writing code, debugging, refactoring, and analyzing repositories.
- Analysis of large volumes of text: reviewing documents, reports, and research, extracting facts.
- Content creation: generating articles, technical descriptions, and summaries of large texts.
- Building reliable AI assistants and agents to automate workflows.
Try GPT-4.1 with no VPN, no limits, and a convenient interface in GPTunneL!