
Updated October 24. Independent results are out from Artificial Analysis, Arena, Bug Hunt Bench and the original StealthMark benchmark, so I start the article with this data, and Moonshot's own figures come closer to the end. I tried to collect every benchmark, the community's take on the release and the 3D demos, to make this review as complete as possible.
So, has the new Kimi K3.1 Pro really caught up with Claude Opus 5.5? The short answer: close, but not yet, and there are two catches I cover below, including suspicions that the model was tuned for benchmarks.
Moonshot released Kimi K3.1 Pro on October 23 - the same day the company itself teased the model's name in a video that morning. In Moonshot's tests the new Kimi runs almost level with Claude Opus 5.5: 65.7% against 66.4% in Terminal-Bench 4.0, and it comes first in six of the fourteen tests. Alongside it came K3.1 Pro Highspeed - the same model, but 2-3 times faster.
I gathered the pre-release leaks in a separate section: the timeline and a video of a voxel pagoda that, according to LuminaBench, was made with K3.1 before launch.
Artificial Analysis Results
In the four tests that Moonshot also reports, Artificial Analysis figures differ from the vendor's by no more than 3.2 points, and in Terminal-Bench 4.0 Artificial Analysis even got a higher score: 67.2 against 65.7.
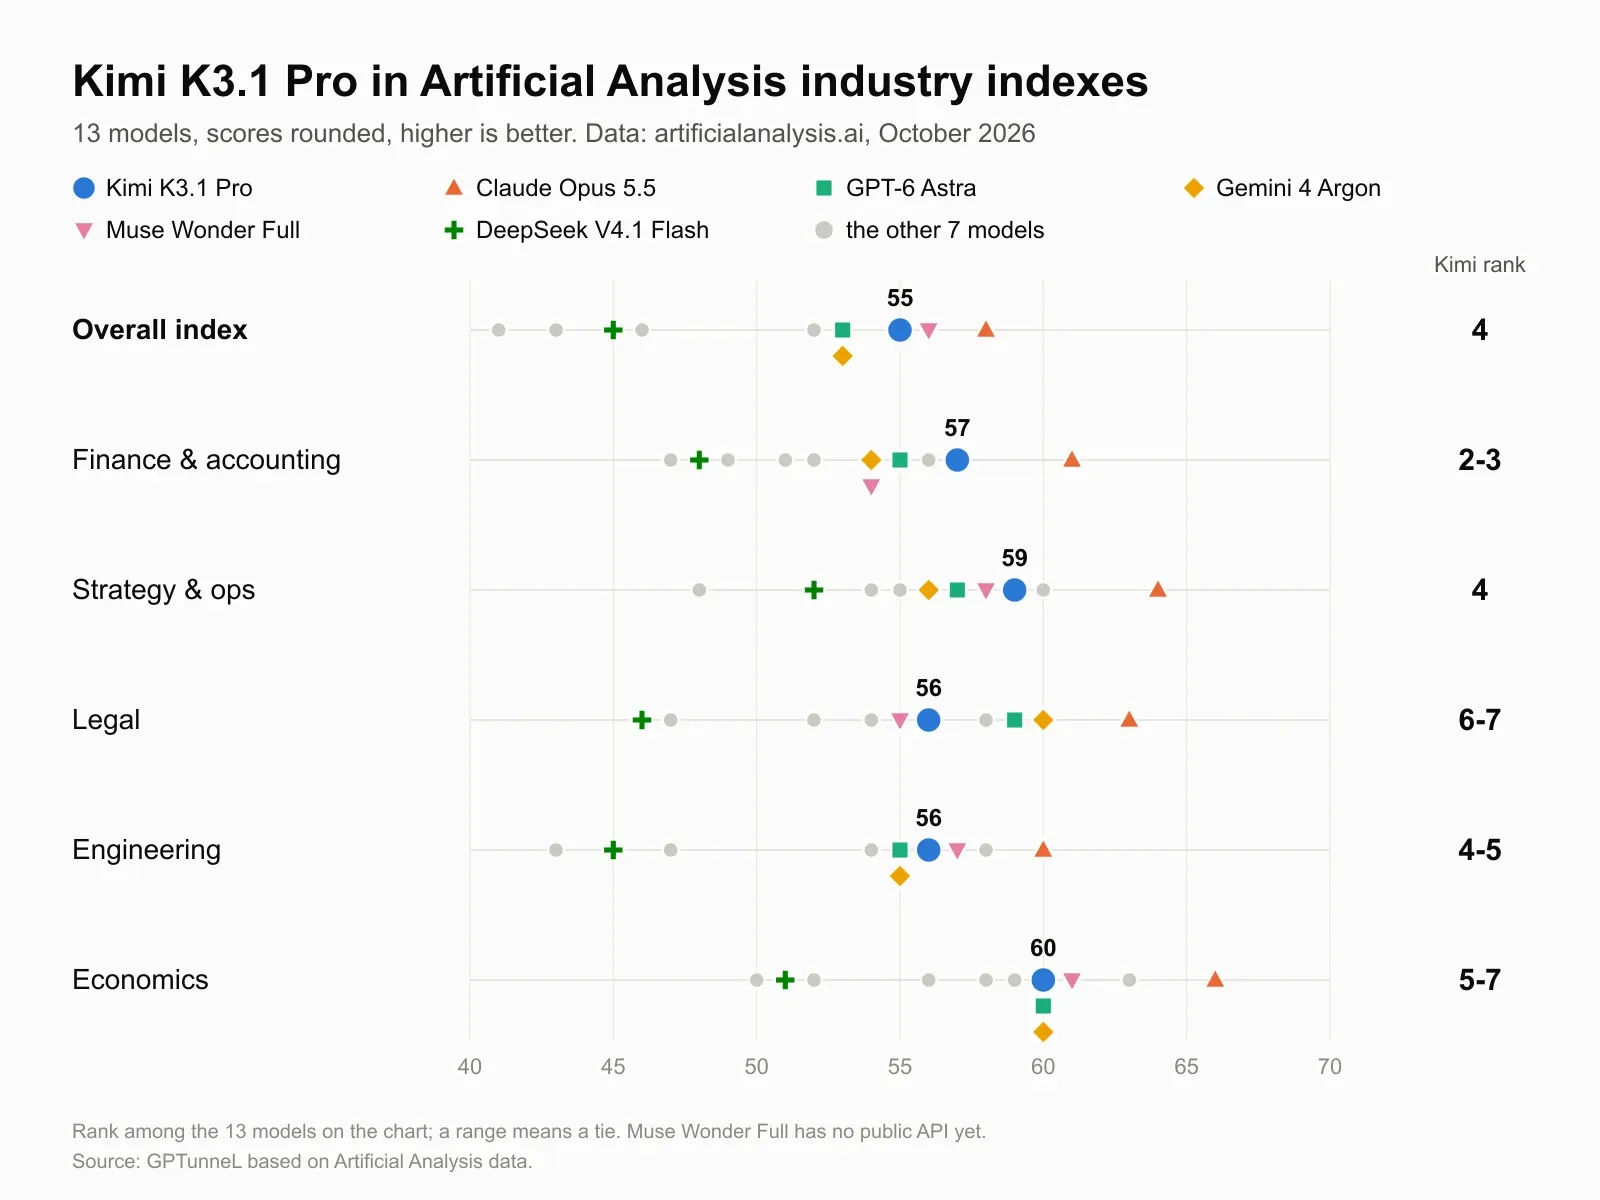
Artificial Analysis runs models on its own set of tests and calculates an overall index plus industry indexes - for finance, legal, engineering and other work. I collected them for 13 models from the top of the ranking.
Show the data table
| Model | Overall | Finance & accounting | Strategy & ops | Legal | Engineering | Economics |
|---|---|---|---|---|---|---|
| Claude Opus 5.5 | 58 | 61 | 64 | 63 | 60 | 66 |
| Claude Sonnet 5.5 | 56 | 57 | 60 | 56 | 58 | 61 |
| Kimi K3.1 Pro | 55 | 57 | 59 | 56 | 56 | 60 |
| Muse Wonder Full | 56 | 54 | 58 | 55 | 57 | 61 |
| Claude Fable 5.1 | 53 | 56 | 60 | 60 | 56 | 63 |
| GPT-6 Astra | 53 | 55 | 57 | 59 | 55 | 60 |
| Gemini 4 Argon | 53 | 54 | 56 | 60 | 55 | 60 |
| GPT-6.1 Sol | 52 | 54 | 57 | 58 | 54 | 59 |
| Muse Wonder | 52 | 51 | 55 | 52 | 54 | 58 |
| Grok 4.7 | 46 | 52 | 54 | 54 | 47 | 56 |
| DeepSeek V4.1 Flash | 45 | 48 | 52 | 46 | 45 | 51 |
| MiniMax-M3.1-Flash | 43 | 49 | 55 | 47 | 43 | 50 |
| Gemini 3.8 Flash | 41 | 47 | 48 | 52 | 43 | 52 |
Source: Artificial Analysis, October 24, 2026.
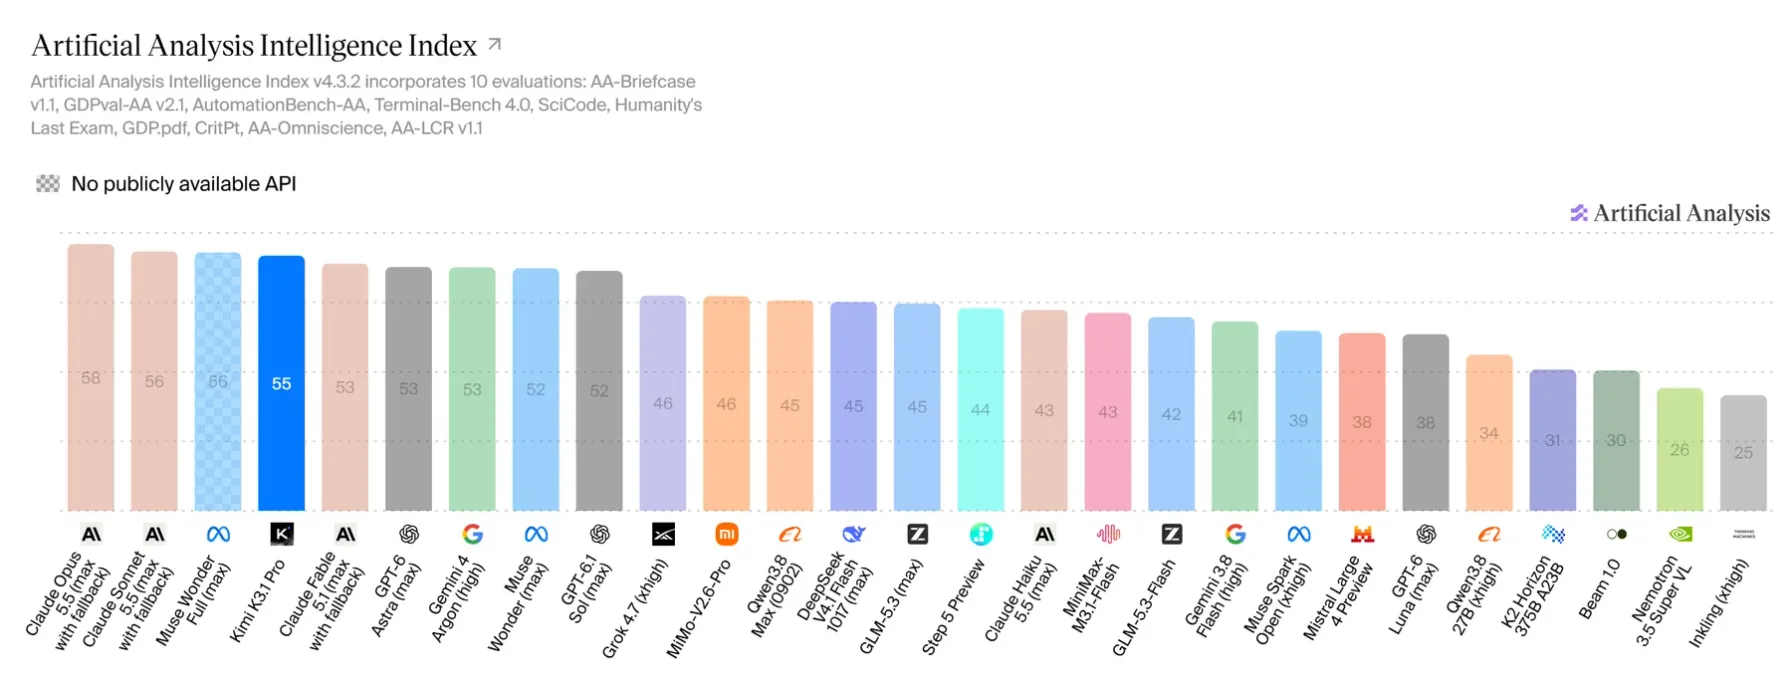
- Overall index - 55 points, 4th of 215 models. Only Claude Opus 5.5 (58), Claude Sonnet 5.5 (56) and Muse Wonder Full (56) rank higher. Kimi K3 had 44, so the gain is 11 points.
- Speed - 77 tokens per second. K3 had 36.9, so the new model is roughly twice as fast. But that is still the middle of the market: 102nd of 186. The first token arrives after 2.89 seconds.
- The model is verbose. Running the index took it 150 million output tokens against a median of 87 million. One index task cost $2.11.
Opus 5.5 leads all six indexes, with a gap of 3 to 7 points over Kimi. K3.1 Pro gets closest in finance: 57 against 61, tied for second and third with Sonnet 5.5. It is furthest behind in legal: 56 against 63, where Kimi is only sixth or seventh, behind Fable 5.1, Gemini 4 Argon, GPT-6 Astra and GPT-6.1 Sol.
Muse Wonder Full has no public API yet, so among the models you can actually put to work, K3.1 Pro is third on the overall index.
Arena Ranking
Twenty-six minutes after the release, Arena showed where the new Kimi landed. On Arena, real users compare models: they get two blind answers and pick the better one.
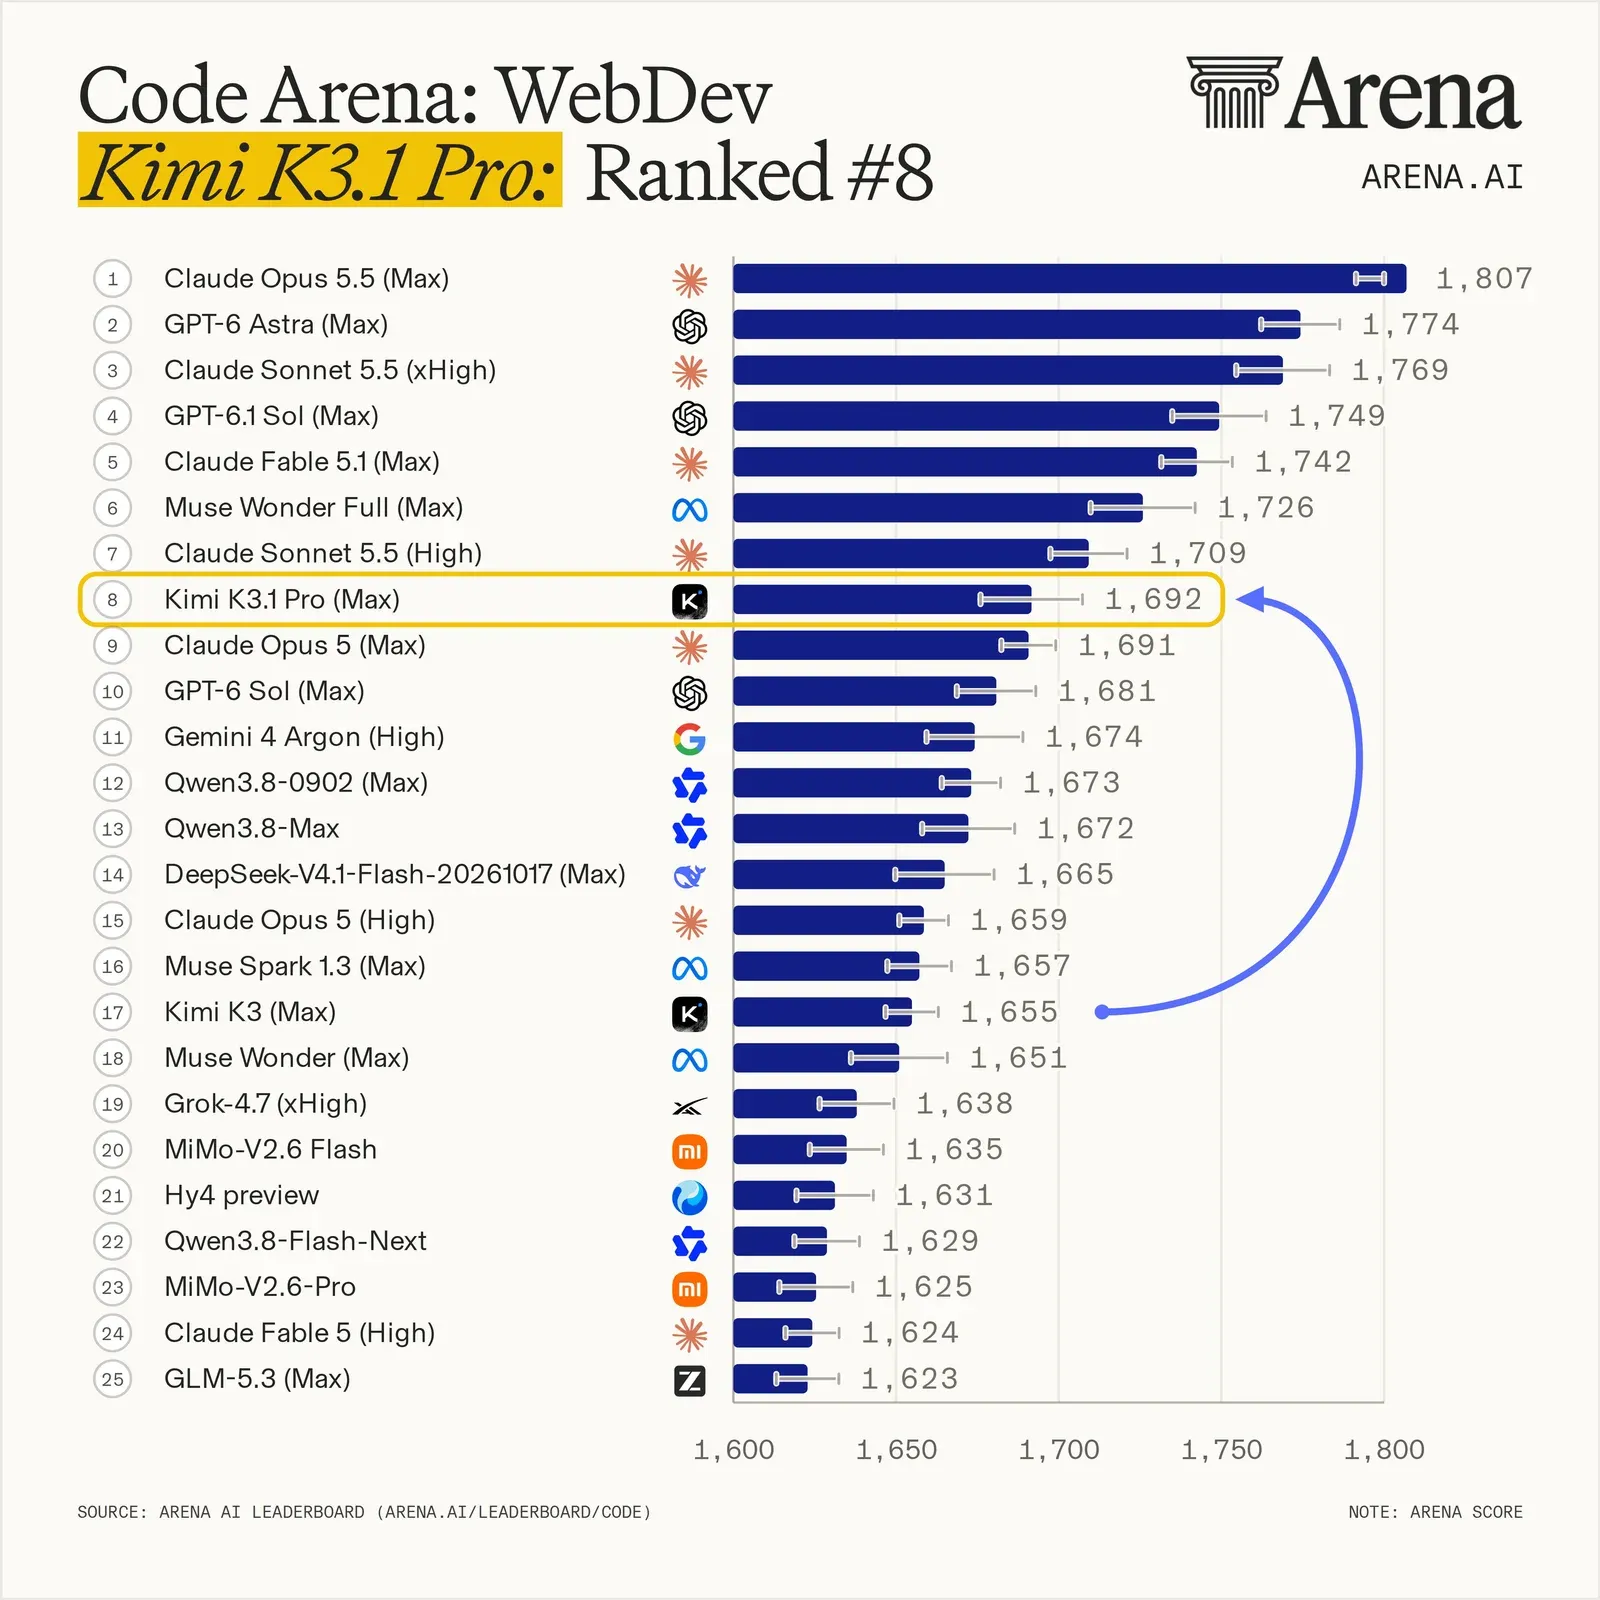
In Code Arena: WebDev, which rates building websites and web apps, Kimi K3.1 Pro took 8th place with 1,692 points - right next to Claude Opus 5 (Max) with 1,691. Compared with Kimi K3 (Max), that is 9 places and 37 points higher. Arena also notes that once the weights are out, K3.1 Pro will be the top open model in this ranking.
Source: Arena on X, October 23, 2026.
Arena also has breakdowns by task type and a separate agent ranking - Agent Arena, which scores models on real sessions: whether the task got done, whether the user was satisfied, and whether the model followed corrections.
| Arena ranking | Kimi K3.1 Pro rank | Kimi result | Leader |
|---|---|---|---|
| Code Arena: WebDev, overall | 8 | 1692 | Claude Opus 5.5 (Max), 1807 |
| WebDev: brand & marketing | 7 | 1704 | Claude Opus 5.5 (Max), 1804 |
| WebDev: data & analytics | 11 | 1606 | GPT-6 Astra (Max), 1683 |
| Agent Arena, overall | 11 | +7.61% | Claude Opus 5.5 (Max), +20.77% |
The new Kimi looks best on brand and marketing tasks: it is seventh there and 26 points ahead of Kimi K3. In data and analytics it is only eleventh, and in Agent Arena it lags the most: its overall score is almost three times lower than Opus 5.5's.
All the ranks are still preliminary. Kimi has between 282 and 515 votes in the breakdowns, so the margin is wide: in analytics the model could end up anywhere from 3rd to 29th. The breakdown figures are from arena.ai as of October 22-23.
The First Catch: Bug Hunt Bench
Bug Hunt Bench is an independent test by Pawel Huryn, author of The Product Compass newsletter. It hides 105 bugs in two real production projects: 45 in a TypeScript VS Code extension (about 28,000 lines) and 60 in a React and Supabase learning platform (about 60,000 lines). Most of the bugs are real regressions from the projects' own history that were rolled back in. The tests stay green, so there are no hints.
Every model gets the same prompt and one attempt per project in its agentic tool. An independent judge checks the result against a hidden answer key without knowing whose work it is. Only the planted bugs count. Even the best models find far from everything: 25 of the 105 bugs have not been fixed by anyone yet.
Kimi K3.1 Pro was run on release day, at the maximum reasoning level and through Moonshot's own API. The harness was not Kimi Code but Anthropic's Claude Code - and that was deliberate: Moonshot itself ran its coding tests for K3.1 Pro in Claude Code, so the author used the same tool. The conditions match those behind the vendor's figures.
The result: 36 of 105, averaged over three runs. That is clearly below the best runs of the other top models, but above the previous Kimi K3.
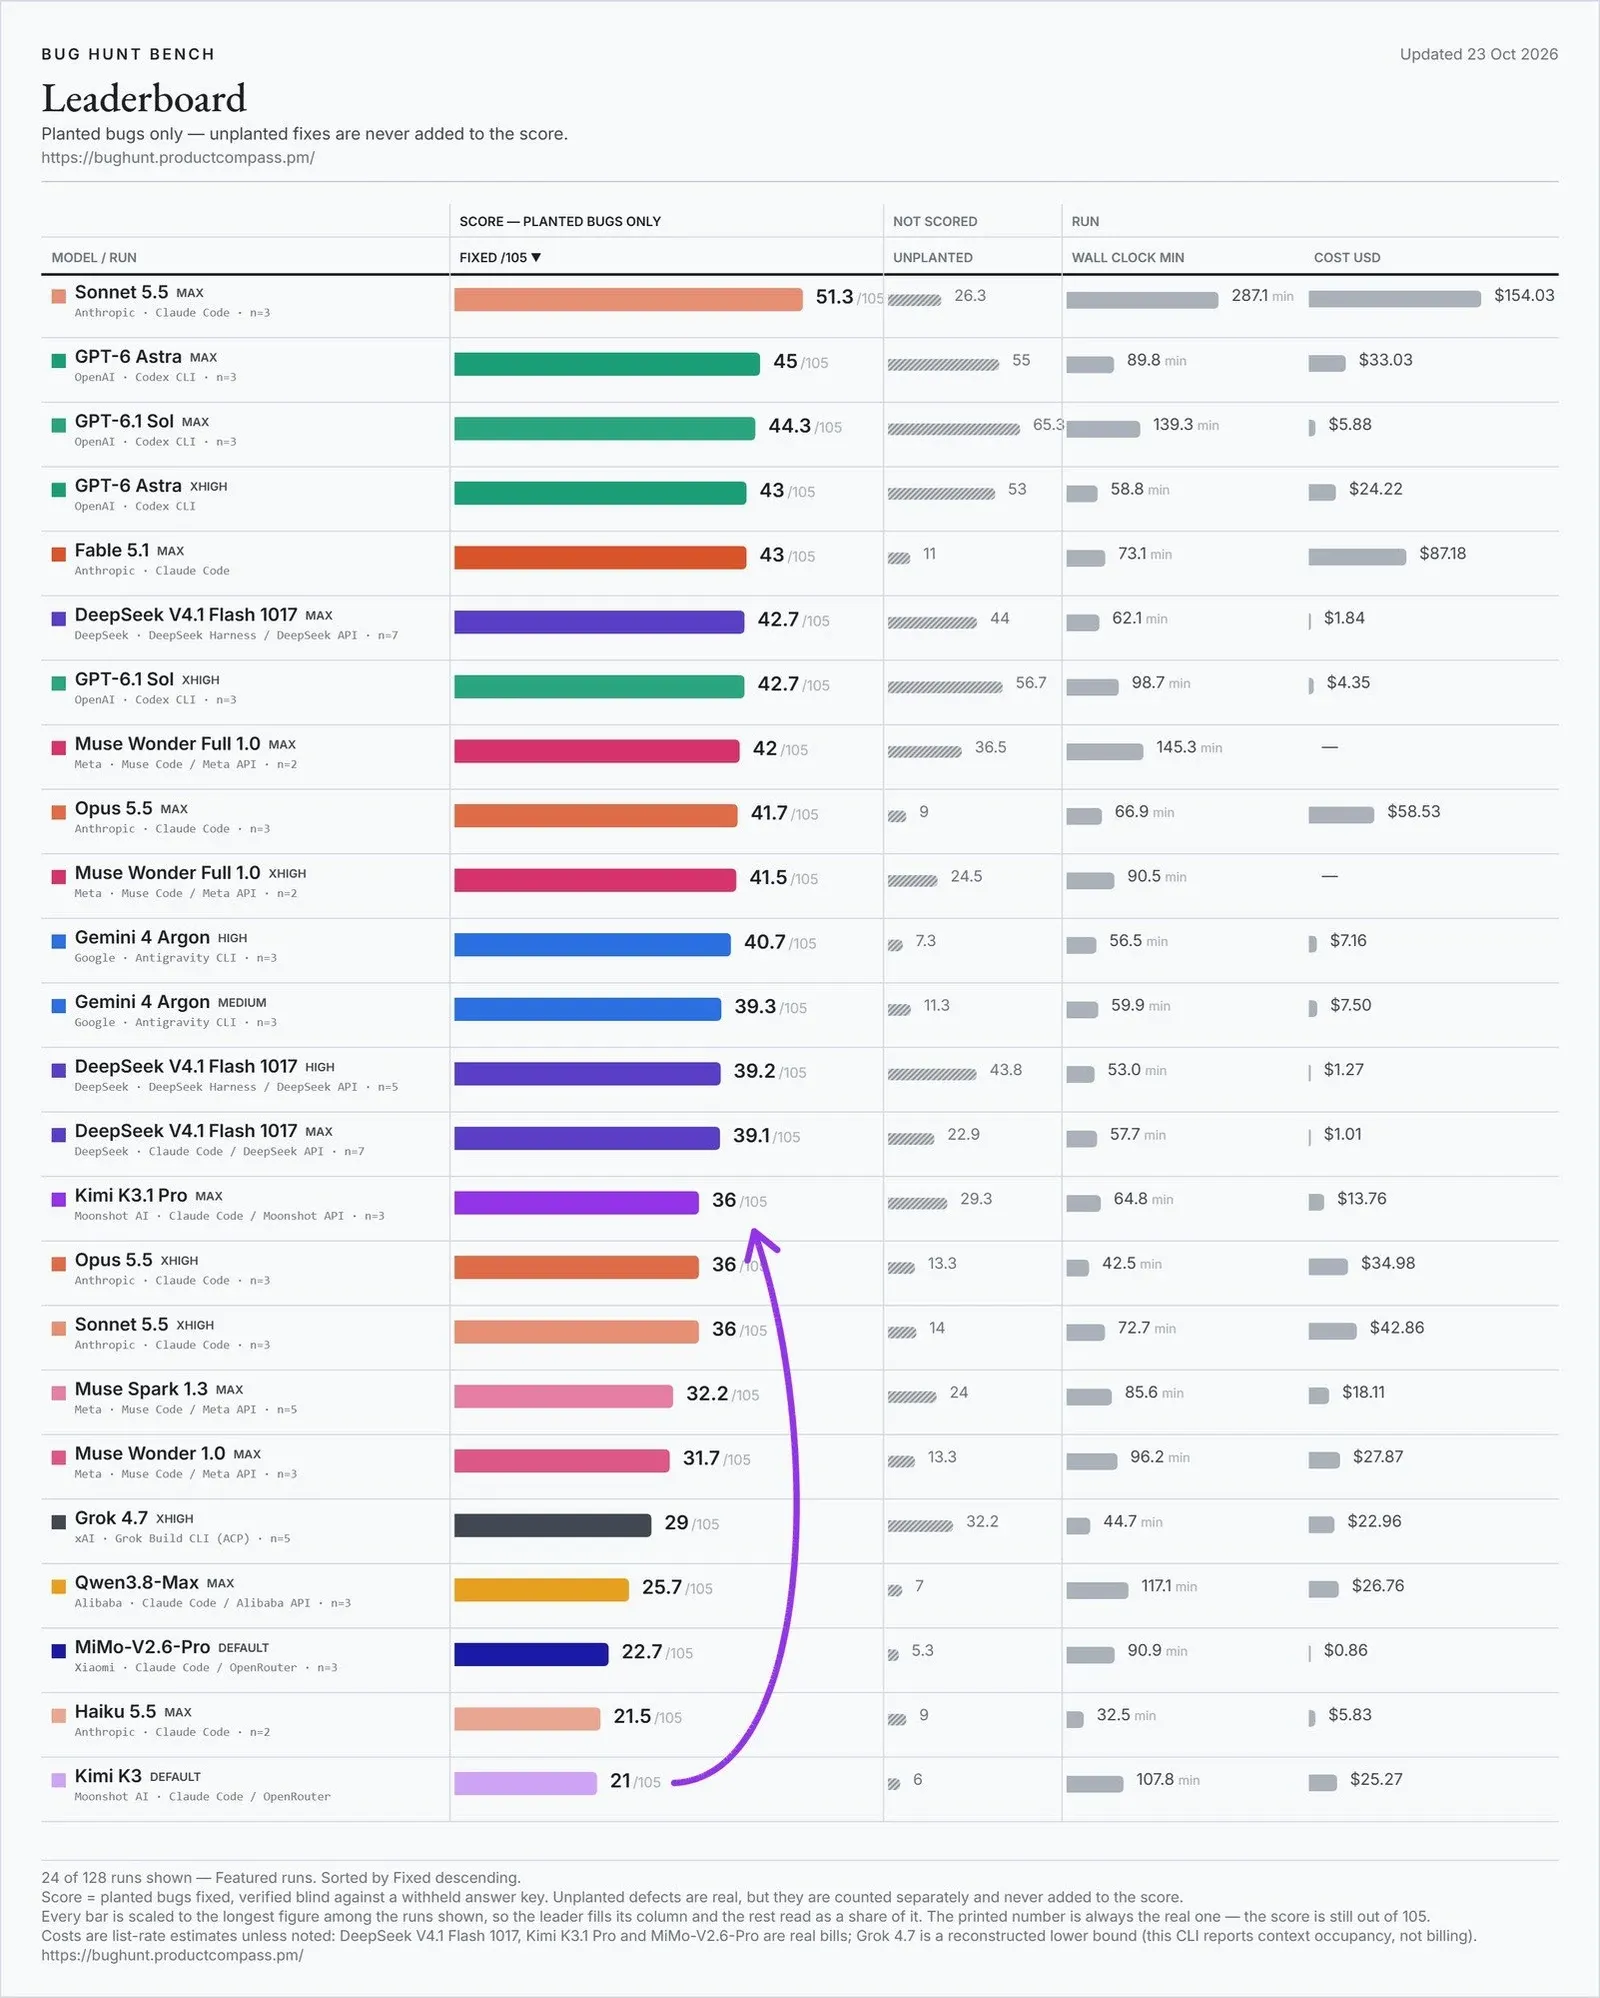
Source: Bug Hunt Bench, updated October 23, 2026.
Show the data table
| Model, level | Fixed of 105 | Time, min | Run cost |
|---|---|---|---|
| Claude Sonnet 5.5, max | 51.3 | 287.1 | $154.03 |
| GPT-6 Astra, max | 45 | 89.8 | $33.03 |
| GPT-6.1 Sol, max | 44.3 | 139.3 | $5.88 |
| Claude Fable 5.1, max | 43 | 73.1 | $87.18 |
| DeepSeek V4.1 Flash, max | 42.7 | 62.1 | $1.84 |
| Muse Wonder Full, max | 42 | 145.3 | - |
| Claude Opus 5.5, max | 41.7 | 66.9 | $58.53 |
| Gemini 4 Argon, high | 40.7 | 56.5 | $7.16 |
| Kimi K3.1 Pro, max | 36 | 64.8 | $13.76 |
| Claude Opus 5.5, xhigh | 36 | 42.5 | $34.98 |
The painful detail: DeepSeek V4.1 Flash, also an open model, fixed almost 7 more bugs and cost 7.5 times less. The test's author drew a blunt conclusion:
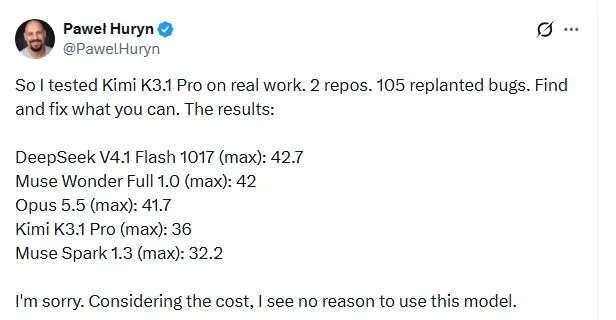
"I'm sorry. Considering the cost, I see no reason to use this model."
Source: Pawel Huryn on X, October 23, 2026.
Kimi's result is also unstable. The three runs scored 36, 42 and 30 bugs - a spread of 12 points. In the third run, on the second project, at around 128,000 tokens of context the model started producing incoherent text in both its reasoning and its final answer, and after 3.9 minutes it finished with no report and not a single change. The API returned no error. That attempt was re-run. Had it been counted as zero, the average would have been 32.
For comparison, the previous Kimi K3 fixed 21 of 105. But it was run through a third-party provider at the default reasoning level, so the gain cannot be credited entirely to the new model.
StealthMark: Another Original Benchmark
StealthMark by Stealth Models is another independent test built on original tasks that models could not prepare for: the exact instructions are kept secret, results are judged blind and every failure counts. It checks physical and spatial reasoning, planning many steps ahead and turning an idea into a precise image. The current version 1.8.5 has 8 tests and 52 models.
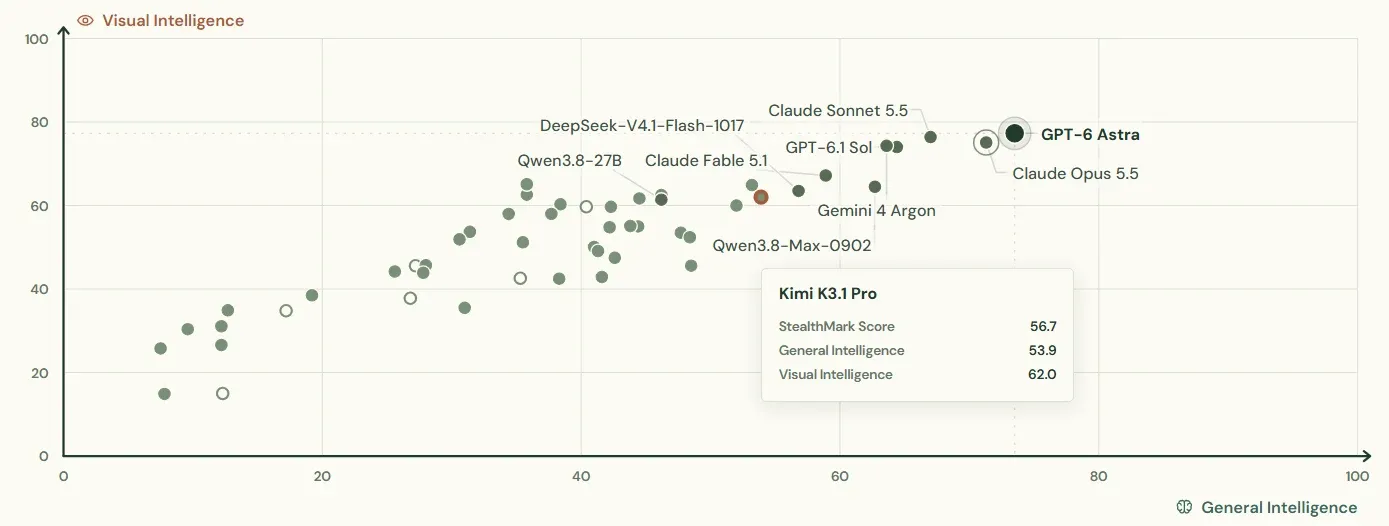
Source: StealthMark, October 23, 2026.
Kimi K3.1 Pro is 11th of 52 with 56.7 points here: 53.9 for general intelligence and 62.0 for visual. Ahead of it are GPT-6 Astra (74.8), Claude Opus 5.5 (72.7) and Claude Sonnet 5.5 (70.3) - and again DeepSeek V4.1 Flash, with 59.2. The previous Kimi K3 scored 50.7 and sits 15th.
How the Release Was Received, and the Second Catch
In the first day after the release, the model was actively discussed in the r/singularity community on Reddit. Here are the main points:
- Limits and queues. People write that a $100 subscription lasts about an hour of normal work, and the five-hour window in Kimi Code runs out in 10 minutes. Another complaint: on new Kimi models it is "rush hour" with a queue at any time of day.
- Skepticism about Moonshot's numbers. The most common reaction is suspicion that the model was tuned for the tests. A concrete argument: Moonshot relies on the old version of Humanity's Last Exam, which has many faulty questions. On the cleaned-up HLE-Diamond, according to Moonshot's own table, K3.1 Pro scores 39.4 against 60.9 for Opus 5.5. The Bug Hunt Bench results show the skepticism is justified: on real bugs in production projects the model fixed 36 of 105 - fewer than Opus 5.5, Fable 5.1 and even DeepSeek V4.1 Flash, although in Moonshot's tests it ran almost level with Opus.
- A "spiky" model. Part of the community thinks Chinese models are strong where demos look good - frontend and 3D - and weaker elsewhere. That matches the numbers: in Terminal-Bench Science, K3.1 Pro scores 38.1 against 68.1 for GPT-6 Astra.
- There is positive feedback too. The author of a separate programming benchmark writes that K3.1 Pro scores the same as Claude Fable 5.1, and the main difference is speed. The discussion also often mentions that once the weights are out, it will set a new bar for open models.
Kimi K3.1 Pro Release Details
Two important details. First: K3.1 Pro is a further-trained K3, not a new model, so the gains come from the same base. Second: Moonshot shipped a fast version right away. Kimi K3 was practically unusable in free mode because of long queues and slow responses, and if Highspeed fixes that, the difference for users will be more noticeable than any gain in the tests.
Moonshot calls K3.1 Pro the first model of the K3.1 series and its most capable open-weight model. According to the company, it is Kimi K3 post-trained with substantially more compute.
| Parameter | Kimi K3.1 Pro | Kimi K3 |
|---|---|---|
| Base | Kimi K3 after additional training | new generation after Kimi K2.6 |
| Architecture | Mixture of Experts, 2.8 trillion parameters, 104 billion of them active | Mixture of Experts, 2.8 trillion parameters, 104 billion of them active |
| Context | 1,048,576 tokens | 1,048,576 tokens |
| Response | up to 131,072 tokens by default | up to 131,072 tokens by default |
| Input | text, images, video | text, images, video |
| Reasoning mode | always on, levels low, high and max, max by default | always on, levels low, high and max, max by default |
| Versions | Pro and Pro Highspeed, the latter 2-3 times faster | a single version, no fast one |
| Open weights | promised by November 4, 2026, license not named yet | published on Hugging Face, license with restrictions on commercial use |
Mixture of Experts is a model design in which only part of the parameters works on each request. That is why a model with 2.8 trillion parameters uses about 104 billion of them for a response.
Reasoning cannot be turned off: the API rejects a request without it with an error. If you need a faster answer, Moonshot recommends the low level.
The model is already available on Kimi.ai, in the Kimi apps for iOS, Android and HarmonyOS, in the Kimi Work desktop app, in Kimi Code and via the API. In Kimi Code, K3.1 Pro is open from the Plus plan, while the 1M-token context and the Highspeed version start at the Pro plan. Highspeed also uses about twice as much of the quota.
Strengths of the New Kimi: Games, 3D and Long Tasks
Moonshot focuses on three areas.
Games as whole projects. According to the company, K3.1 Pro works confidently with the Unity, Unreal Engine and Godot game engines - not with separate scripts, but with the project as a whole.
Video source: the Kimi K3.1 Pro tech blog, October 23, 2026.
Parametric 3D modeling. This is when a model is built not by hand but with code and parameters: change a number and the part changes. K3.1 Pro writes and runs scripts for Blender and CAD software on its own, without MCP connectors - the ready-made modules usually used to connect a model to third-party programs.
Video source: the Kimi K3.1 Pro tech blog, October 23, 2026.
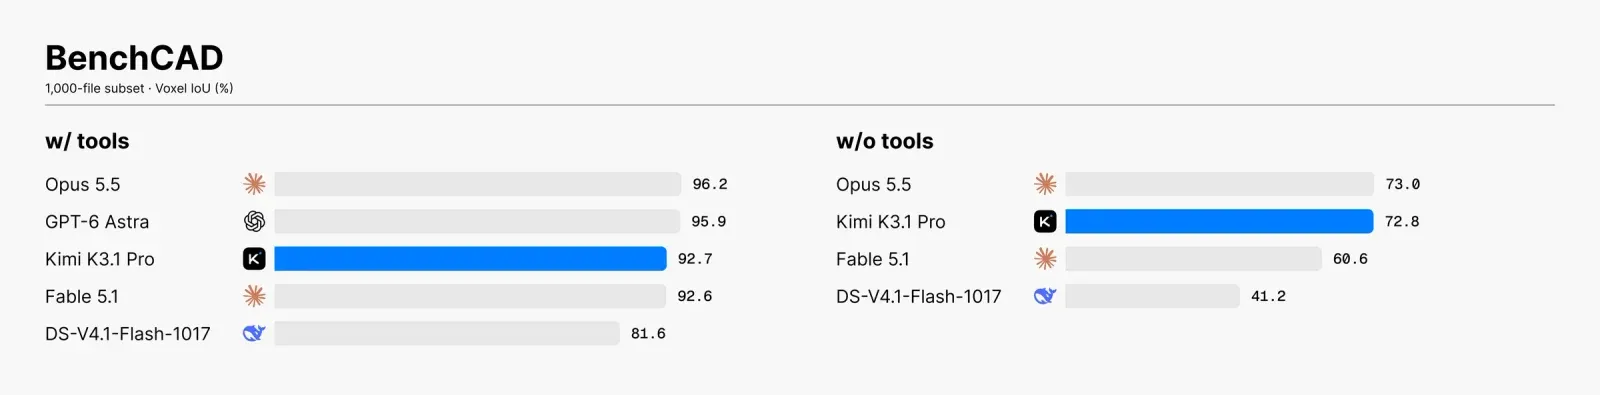
In BenchCAD, the model reconstructs a 3D part from images taken from several angles, and the result is compared with the original. With tools K3.1 Pro is third, and without tools it trails Claude Opus 5.5 by just 0.2 points and beats Claude Fable 5.1 by 12.
Together with the model, Moonshot launched 3D Make on kimi.ai and in the Kimi app: you can view and edit a 3D model right in the browser and then download it ready for 3D printing.
Long tasks. As an example, Moonshot had the model build a walking simulator on human-atlas - an open anatomical model of the human body with 296 skeletal components, including cartilage, and 402 muscles. Over 167 missions and 420 independent reviews, K3.1 Pro brought the simulator to continuous walking with alternating strides for 11.2 seconds, and found and fixed 36 errors in the shoulder muscle calculations.
Video source: the Kimi K3.1 Pro tech blog, October 23, 2026.
What Moonshot's Tests Show
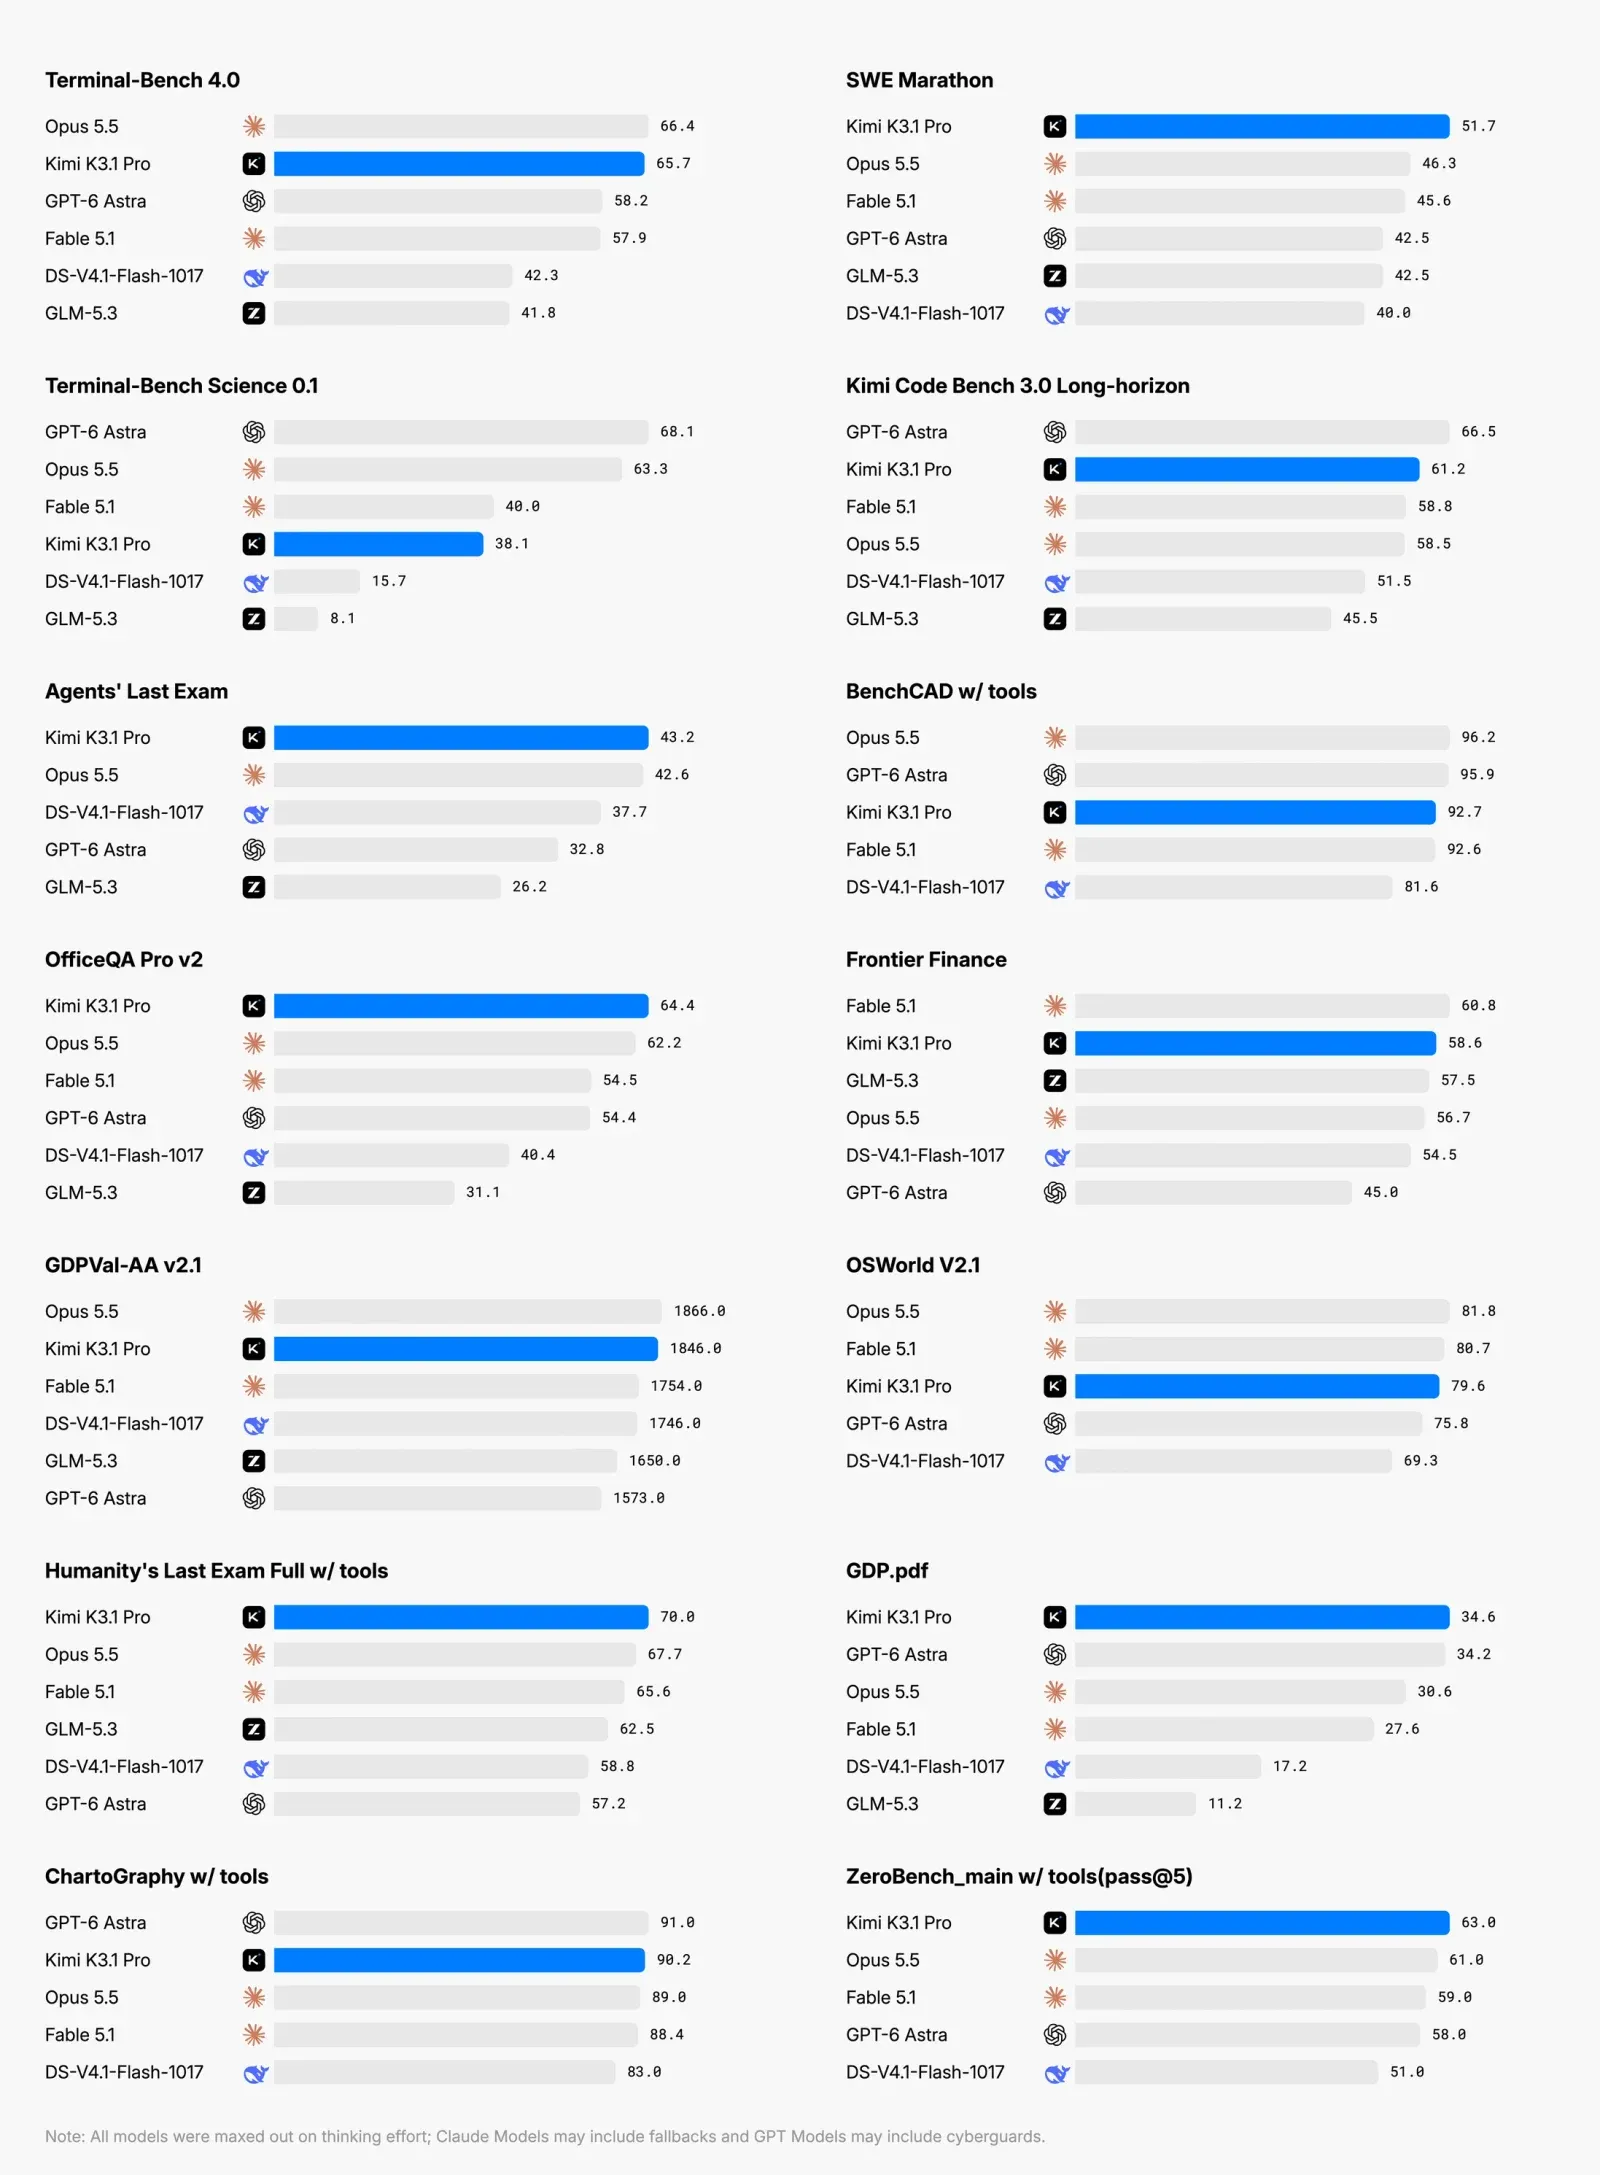
Chart source: the Kimi K3.1 Pro tech blog, October 23, 2026.
Moonshot compared K3.1 Pro with Claude Opus 5.5, GPT-6 Astra, Claude Fable 5.1, DeepSeek V4.1 Flash and GLM-5.3 across 14 tests. All models were set to the maximum reasoning level. All 14 results against the three closest rivals are in the table below.
Show the data table
| Test | Kimi K3.1 Pro | Claude Opus 5.5 | GPT-6 Astra | Claude Fable 5.1 |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 65.7 | 66.4 | 58.2 | 57.9 |
| SWE Marathon | 51.7 | 46.3 | 42.5 | 45.6 |
| Kimi Code Bench 3.0 Long-horizon | 61.2 | 58.5 | 66.5 | 58.8 |
| Terminal-Bench Science 0.1 | 38.1 | 63.3 | 68.1 | 40.0 |
| Humanity's Last Exam with tools | 70.0 | 67.7 | 57.2 | 65.6 |
| Agents' Last Exam | 43.2 | 42.6 | 32.8 | - |
| OSWorld V2.1 | 79.6 | 81.8 | 75.8 | 80.7 |
| OfficeQA Pro v2 | 64.4 | 62.2 | 54.4 | 54.5 |
| Frontier Finance | 58.6 | 56.7 | 45.0 | 60.8 |
| GDPval-AA v2.1, rating | 1846 | 1866 | 1573 | 1754 |
| BenchCAD with tools | 92.7 | 96.2 | 95.9 | 92.6 |
| BenchCAD without tools | 72.8 | 73.0 | - | 60.6 |
| ChartoGraphy with tools | 90.2 | 89.0 | 91.0 | 88.4 |
| GDP.pdf | 34.6 | 30.6 | 34.2 | 27.6 |
| ZeroBench with tools, pass@5 | 63.0 | 61.0 | 58.0 | 59.0 |
K3.1 Pro comes first in six tests: SWE Marathon, Humanity's Last Exam, Agents' Last Exam, OfficeQA Pro v2, GDP.pdf and ZeroBench. In Terminal-Bench 4.0 (command-line tasks), OSWorld (operating a computer through its interface) and GDPval (work tasks from different professions) it trails Opus 5.5 by 0.7-2.2 points or 20 rating points.
Finance and Office Work
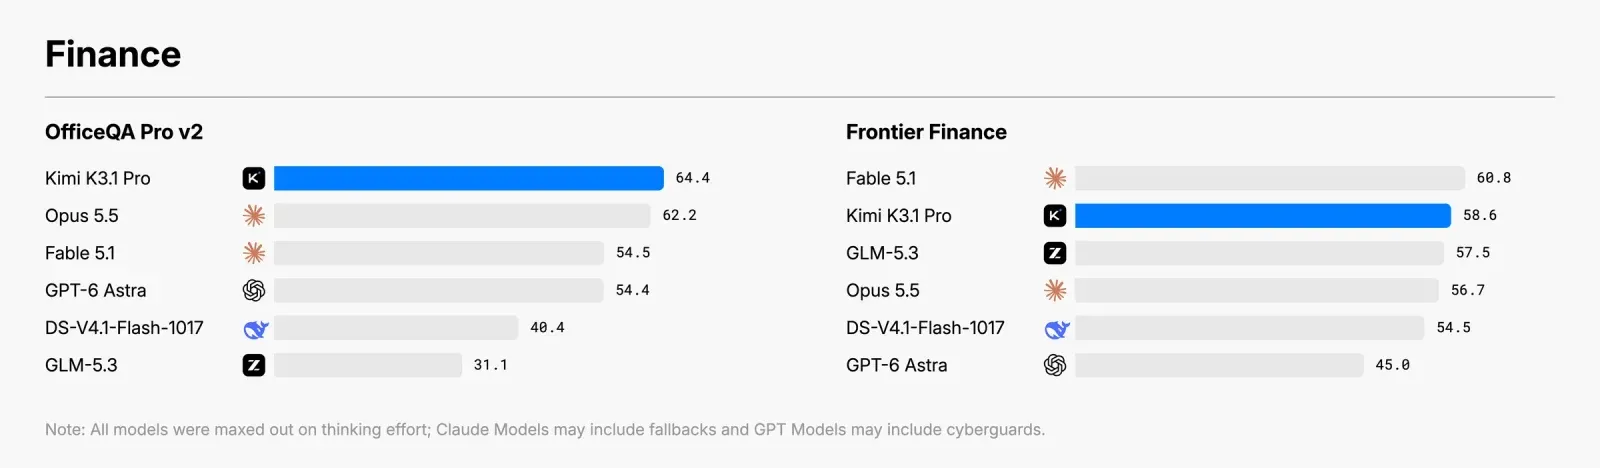
In the public OfficeQA Pro v2 test (questions about office documents) K3.1 Pro is first with 64.4, and in Frontier Finance it is second with 58.6, behind Claude Fable 5.1.
Fewer Made-Up Facts
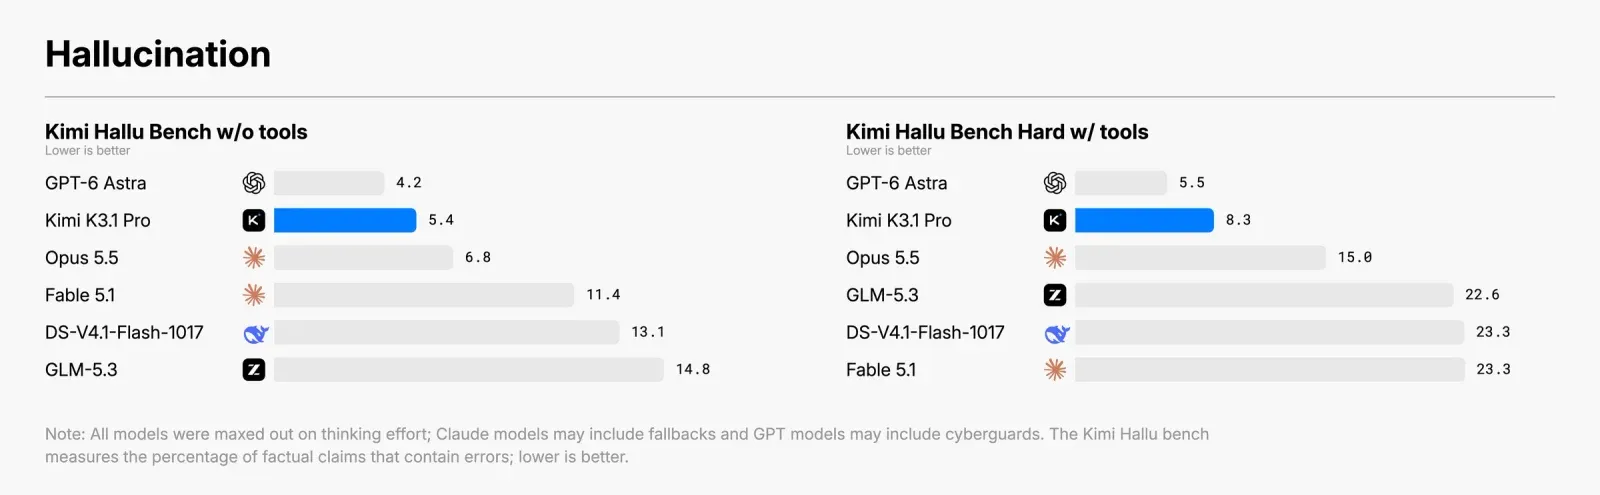
On its Kimi Hallu Bench Hard stress test, Moonshot measured what share of the claims in answers turned out to be false. K3 had 23.4%, K3.1 Pro has 8.3%. For comparison, Claude Opus 5.5 has 15.0% in the same test and GPT-6 Astra 5.5%.
Moonshot itself notes that the test was deliberately built from hard examples, and these percentages are not the same as the error rate in everyday use.
Cybersecurity Was Cut Back on Purpose
For the open-weight version, Moonshot removed cybersecurity data from training: open weights, the company says, should not push the frontier of what models can do in hacking. In the xdev-bench-hard test, the version without this cleanup scored 90.5, while the final K3.1 Pro scored 81.0, below closed models such as GPT-5.6 Sol with 100.
What One Task Costs
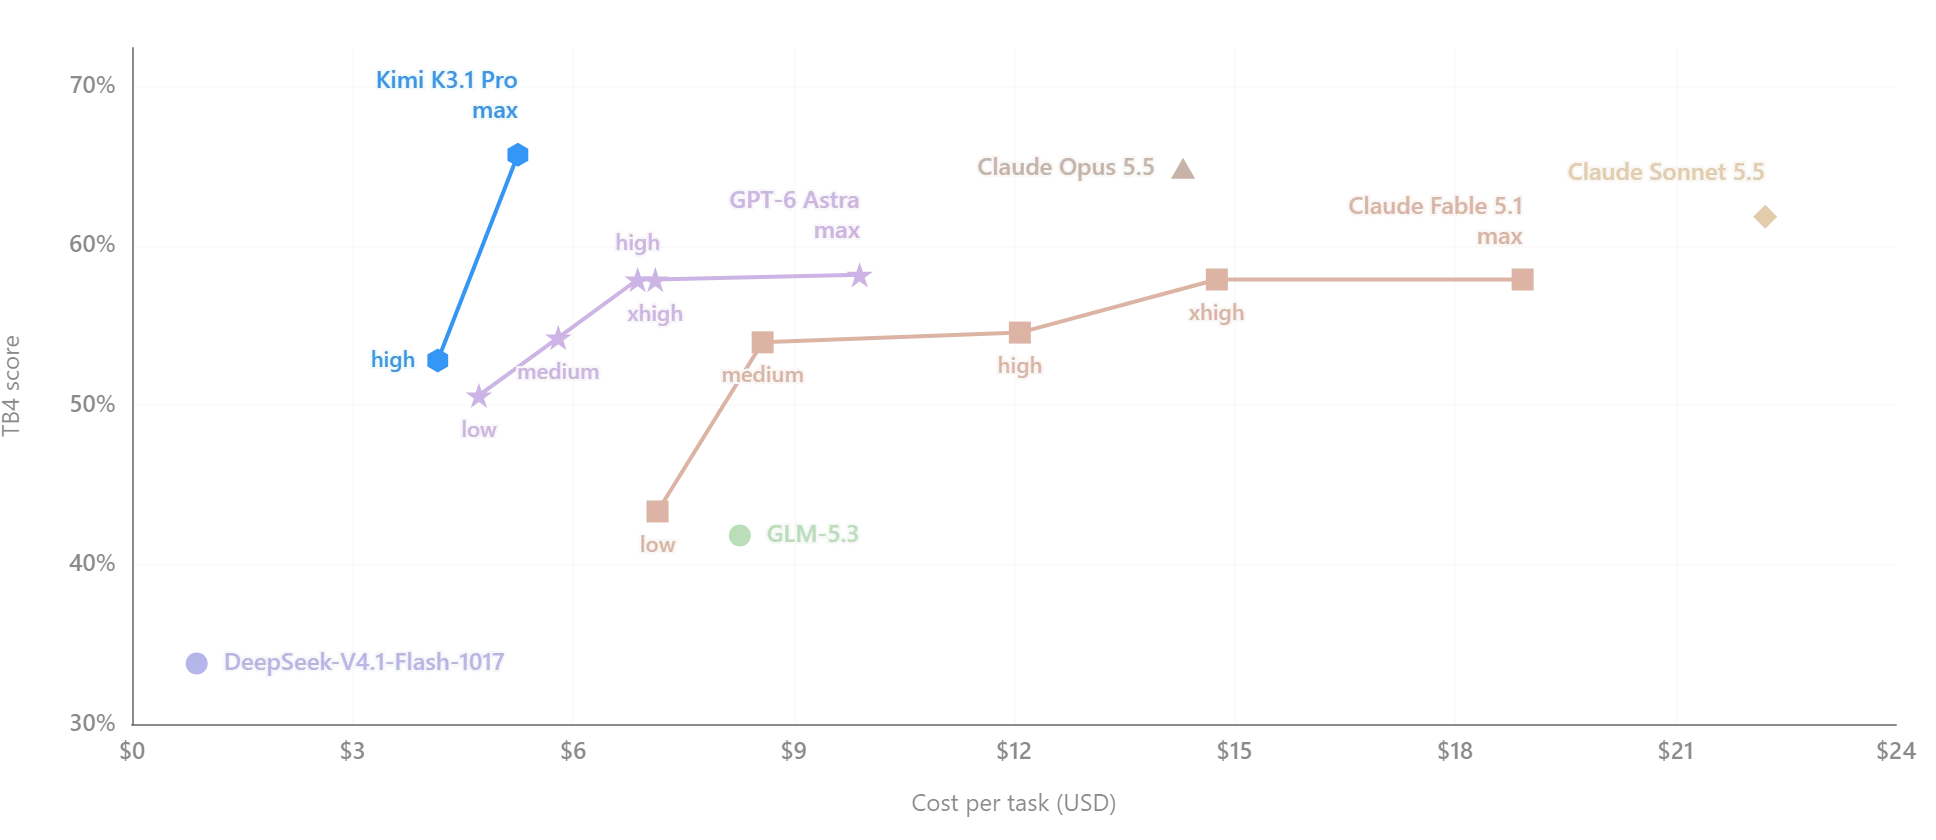
For choosing a model, Moonshot's most useful chart is the Terminal-Bench 4.0 score against the average cost of one task. Scores and costs for all models except DeepSeek come from tbench.ai, the test's own site, and for DeepSeek from Artificial Analysis.
Show the data table
| Model | Reasoning level | Score | Cost per task |
|---|---|---|---|
| Kimi K3.1 Pro | max | 65.7% | $5.25 |
| Kimi K3.1 Pro | high | 52.8% | $4.16 |
| Claude Opus 5.5 | max | 64.85% | $14.30 |
| Claude Sonnet 5.5 | max | 61.82% | $22.22 |
| GPT-6 Astra | max | 58.18% | $9.90 |
| GPT-6 Astra | high | 57.88% | $6.88 |
| GPT-6 Astra | low | 50.61% | $4.72 |
| Claude Fable 5.1 | xhigh | 57.88% | $14.76 |
| Claude Fable 5.1 | max | 57.88% | $18.92 |
| GLM-5.3 | - | 41.82% | $8.27 |
| DeepSeek V4.1 Flash | - | 33.8% | $0.88 |
At the maximum level K3.1 Pro even scores slightly more than Claude Opus 5.5 - 65.7% against 64.85% - while a task costs 2.7 times less: $5.25 against $14.30. GPT-6 Astra at max costs almost twice as much and scores 7.5 points lower.
Saving on the reasoning level does not pay off here. At high, a task is only $1.09 cheaper, while the score drops from 65.7% to 52.8% - below GPT-6 Astra at high.
In the summary chart Opus 5.5 has 66.4%, while here it has 64.85%: the figures from Moonshot's summary and from tbench.ai differ.
What Is Still Missing
- Open weights. They are promised by November 4, with no license named. Kimi K3's weights came out with restrictions on commercial use.
- Confirmation about Kibitz. The community took the anonymous model on Arena for K3.1, but neither Moonshot nor Arena confirmed it.
The Bottom Line: What the Kimi K3.1 Pro Release Means for Regular Users
In short: K3.1 Pro is a strong model and a big step forward for Kimi, but not a replacement for Opus 5.5. In Moonshot's tests it runs almost level with Opus, while in independent measurements it falls behind: 55 against 58 on the Artificial Analysis index, 36 against 41.7 bugs fixed in Bug Hunt Bench. Below is a breakdown by task.
Kimi K3.1 Pro did not lead a single independent benchmark, and in several tests it lost even to the much cheaper DeepSeek V4.1 Flash. Despite the good results, many people are skeptical about using Kimi for their work because limits get used up fast and the cost per task is not low overall (especially for a Chinese model).
- Agentic coding on real projects. Here I would stay with Opus 5.5 or Sonnet 5.5 for now. In Bug Hunt Bench, K3.1 Pro fixed fewer bugs than all the top models, and in Agent Arena it is only eleventh. If you need a cheap open model for code, DeepSeek V4.1 Flash did better in the same Bug Hunt and was 7.5 times cheaper.
- Websites, landing pages and 3D. This is the new Kimi's strong side, and it is worth trying. In WebDev on Arena it is eighth, on par with Claude Opus 5, and seventh on brand and marketing tasks. In 3D modeling without tools it trails Opus 5.5 by 0.2 points.
- Finance and office documents. Also a workable option: on the Artificial Analysis finance index, K3.1 Pro shares second and third place with Sonnet 5.5, and in Moonshot's office documents test it comes first.
- Scientific tasks. Not the best choice: in Terminal-Bench Science it scores almost half as much as GPT-6 Astra.
A separate note on speed and money. K3.1 Pro is twice as fast as K3, but that is still the middle of the market, and its answers are verbose - running the Artificial Analysis index took 1.7 times more tokens than an average model. At the same time, a Terminal-Bench 4.0 task costs 2.7 times less than with Opus 5.5.
I see two catches. The first is limits and queues: subscriptions run out fast, and in the free version you can barely get to the model right now. The second is stability on long tasks: in Bug Hunt Bench, at 128,000 tokens of context the model started producing incoherent text, even though the stated context is 1 million.
The most interesting moment, in my view, will be November 4, when the weights come out. If Moonshot keeps its promise, this will be the strongest open model you can run yourself, and that is when the price-to-quality ratio could become truly attractive. The Arena ranks are still preliminary, so I would draw final conclusions in a week or two and after testing on your own tasks.
How K3.1 Surfaced Before Release
The name K3.1 kept surfacing in leaks for several weeks, and on release day Moonshot showed it in a video itself.
- September 19. On Kimi's verified account on Zhihu, a Chinese question-and-answer platform, an uncaptioned post appeared: a long string of digits of pi after "3.1". The community read it as a hint at version 3.1.
- Late September. According to reports, the identifier "kimi-k3-1" was spotted in the Moonshot API.
- October 21. LuminaBench, an author of AI news and benchmarks on X, found a model-switching rule pointing to "k3.1" in Kimi Code.
- October 22. In Code Arena battles, where users don't know which model they will get, an anonymous model named Kibitz appeared. The community linked it to Kimi: according to AGTP, it garbled Moonshot's special tokens the same way other Kimi models do, and earlier Kimi models ran on Arena under similar names - Kiwido, Kiwire, Kivine.
- October 23, 01:41 UTC. Kimi's official account posted a 24-second video in which the Kimi Code terminal shows the line "Model: Kimi K3.1".
- October 23, 04:46 UTC. Arena wrote that a new Moonshot model was coming soon.
- October 23, 17:15 UTC. K3.1 Pro was released.
Before the release, LuminaBench posted several videos that, according to him, were made with K3.1 under the name Kibitz. The most striking is a voxel pagoda next to the work of other models. It is one prompt and one attempt, so it should not be taken as a model comparison.
Video source: @LuminaBench on X, October 22, 2026.
Sources
- Kimi K3.1 Pro Tech Blog: Advancing Open Intelligence, 23.10.2026 - the official announcement, 14 tests, hallucinations, cybersecurity.
- Kimi.ai on X: the K3.1 Pro release, 23.10.2026 - 2.8 trillion parameters, 104 billion active, context.
- Kimi K3.1 Pro quickstart - reasoning mode, response length, image and video input.
- Kimi K3 quickstart - K3 specs for comparison: response length, reasoning mode, input.
- Kimi API pricing - K3.1 Pro and Highspeed rates.
- Models in Kimi Code - plans, context and quota use.
- Kimi.ai on X: the video with "Model: Kimi K3.1", 23.10.2026.
- Arena.ai on X: Kimi K3.1 Pro 8th in Code Arena: WebDev, 23.10.2026 - 1,692 points, on par with Claude Opus 5 (Max).
- Arena.ai on X, 23.10.2026 - "A new model from @Kimi_Moonshot is coming."
- ChainCatcher: Kimi's video and the K3.1 backstory, 23.10.2026 - the "kimi-k3-1" identifier in the API.
- LuminaBench: Kimi K3.1 looks to be getting close, 21.10.2026 - K3.1 mentioned in Kimi Code.
- AGTP on X: the mystery model Kibitz on Arena, 22.10.2026 - tokenizer and codenames.
- Kimi K3.1 Pro on Artificial Analysis - overall and industry indexes, speed, cost per task.
- Bug Hunt Bench, 23.10.2026 - 105 hidden bugs in two projects, three Kimi K3.1 Pro runs; method and raw data.
- StealthMark, 23.10.2026 - original tasks on physical and spatial reasoning, planning and visual skills.
- Kimi K3 on Artificial Analysis - K3's speed and license.